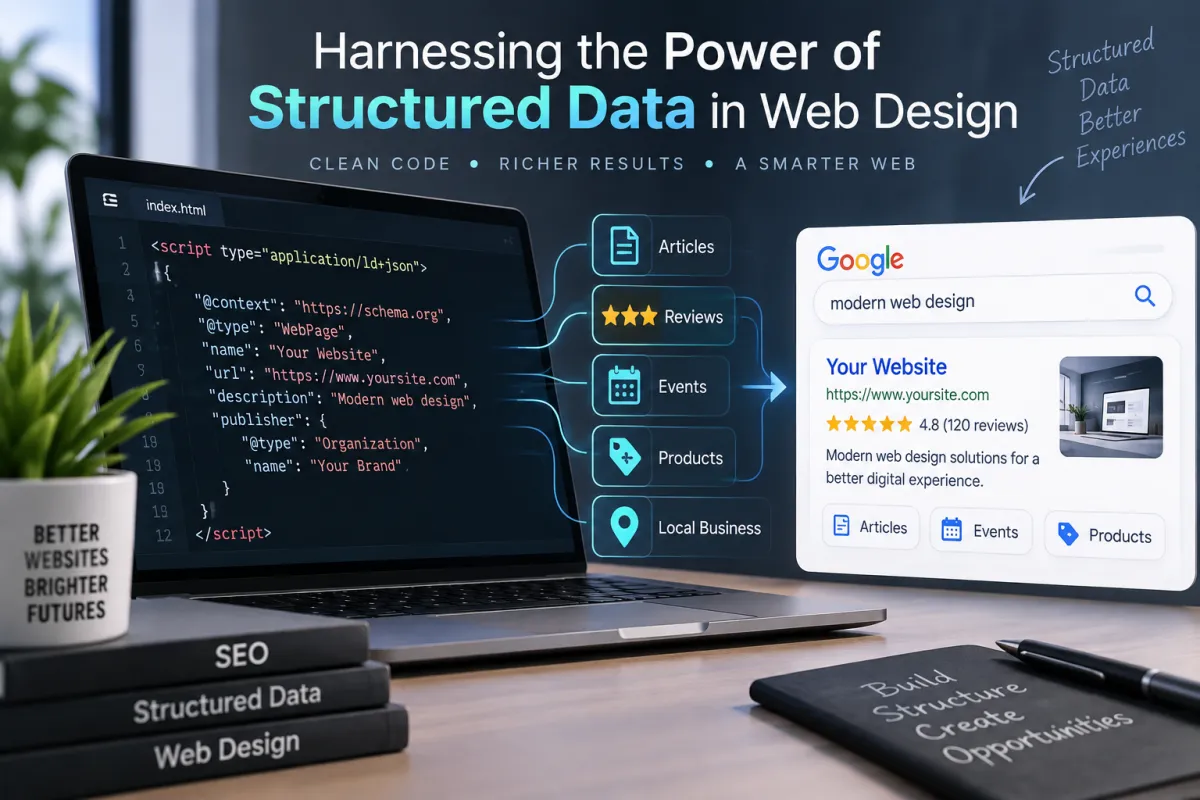
Harnessing the Power of Structured Data in Web Design
Structured data gives search engines a machine-readable description of what a web page contains and what its individual elements mean. Using Schema.org vocabulary with formats such as JSON-LD can explicitly identify products, organisations, articles, offers, reviews, breadcrumbs and other entities. When structured data is accurate and matches visible page content, it can help search engines understand and classify that content and may make eligible pages available for enhanced search features and rich results. For web designers and ecommerce businesses, the important shift is to stop treating schema markup as an SEO patch added after a site is built. It should be considered alongside semantic HTML, information architecture, content modelling and page templates from the beginning.
Web design has always had two audiences.
The first is obvious: people.
They see the typography, images, navigation, product cards, buttons, menus and carefully considered whitespace. They decide whether a page feels trustworthy, whether they understand the offer and whether they want to keep browsing.
The second audience sees something rather different.
Search engines encounter HTML, text, metadata, links and machine-readable signals. They need to determine whether Greenwich is a place, £79.99 is a product price, 4.8 is a rating, or a string of text beside a photograph is the name of an author, organisation or product.
That difference is precisely where structured data becomes valuable.
Harnessing the Power of Structured Data in Web Design means designing pages that communicate effectively to humans while providing explicit, structured clues that machines can interpret.
And that makes structured data much more interesting than a few snippets of code hidden behind an attractive website.
What Is Structured Data in Web Design?
Structured data is a standardised, machine-readable way of describing information on a webpage.
Ordinary HTML gives a browser the structure required to render a page. Semantic HTML can provide additional meaning through elements such as <article>, <nav>, <header> and <footer>. Structured data goes further by explicitly describing the entities, attributes and relationships represented by the page content.
Imagine an ecommerce product page displaying:
the product name;
an image;
a description;
a price;
currency;
availability;
a brand;
customer ratings; and
reviews.
A shopper can usually understand those relationships immediately.
A machine needs more explicit context.
With structured data markup, those pieces of information can be described using a recognised data vocabulary. The page can identify the main entity as a Product, for example, while properties can describe its name, image, description, offers, price, priceCurrency and availability.
That creates an additional semantic layer behind the visual interface.
In simplified terms:
Web design → HTML → semantic markup → structured data → entities and properties → machine understanding
For businesses thinking about a wider ecommerce marketing strategy, this distinction matters. A website isn't merely a collection of attractive pages. It is also a structured source of information that search crawlers must discover, interpret and index.
Structured data isn't the same thing as metadata
The terms overlap, but they shouldn't automatically be treated as interchangeable.
Metadata broadly describes information about a resource. A title element and meta description, for instance, provide information about a webpage.
Structured data describes information according to a defined structure or vocabulary, allowing relationships to be expressed much more explicitly.
Consider:
Product
├── name
├── image
├── description
├── brand
├── offers
│ ├── price
│ ├── priceCurrency
│ └── availability
└── aggregateRating ├── ratingValue └── ratingCount
That hierarchy is what makes structured content powerful.
Instead of hoping that a search engine correctly infers how several independent pieces of page content relate to one another, structured data provides additional clues about their meaning.
Schema.org: Giving the Web a Shared Vocabulary
Structured data needs a vocabulary.
One of the most important is Schema.org.
The Schema.org vocabulary provides types and properties that websites can use to describe entities in a consistent way. Rather than every developer inventing a different method of saying, "This is a product and this number is its price," a shared vocabulary establishes recognisable definitions.
A schema type describes the kind of entity involved.
Examples include:
Schema type | What it can describe |
|---|---|
| A product or service |
| A business or organisation |
| A person |
| An article or piece of editorial content |
| A particular physical business |
| An event |
| A recipe |
| Video content |
| A software application |
| An offer associated with an item |
Schema properties then supply information about those entities.
For an Article, that might include headline, author, image and datePublished.
For a Product, properties might identify name, description, brand, offers and aggregateRating.
And an Offer can itself contain properties such as price, priceCurrency, availability and seller.
This creates a network of entities and entity relationships rather than a flat collection of disconnected keywords.
Good structured data doesn't merely tell a machine what words appear on a page. It helps describe what those words represent and how the information relates.
That distinction sits at the heart of the semantic web.
From Keywords to Entities: Why Semantic Web Design Matters
Traditional SEO discussion often revolves around keywords.
Keywords still matter because language matters. But search engines also need to understand things.
A company is a thing. A product is a thing. An author is a thing. An address is a thing. A review is a thing. Each can have attributes, and each can be related to other entities.
Suppose a page contains:
Atlas Desk Lamp — £59 — In Stock — Rated 4.7/5
To a human, the meaning is obvious.
Structured data can make the relationships explicit:
Atlas Desk Lamp →
Product£59 → an
Offerwith a price and currencyIn Stock → availability
4.7/5 →
AggregateRating
This is the transition from simply publishing words to creating machine-readable content.
It also illustrates why structured data belongs in conversations about content architecture, information architecture and content modelling, not only technical SEO.
If a website has clearly defined page templates and predictable data fields, producing accurate structured data becomes easier. If product information is scattered inconsistently across templates, schema implementation becomes correspondingly harder.
Think of schema as part of the information architecture
A useful way to approach structured data strategy is to ask four questions for every important page template:
What is this page fundamentally about?
What is the primary entity?
Which attributes of that entity are genuinely present on the page?
What relationships exist between this entity and other entities?
An ecommerce product page might revolve around a Product.
An editorial guide could revolve around an Article.
A company page could describe an Organization.
A navigational trail could be represented through BreadcrumbList.
Once those entities are mapped to the website architecture, schema implementation becomes less about inserting isolated pieces of code and more about designing a consistent metadata architecture.
How JSON-LD Fits Into Structured Data
Schema.org supplies the vocabulary, but that vocabulary still needs to be expressed in a format machines can process.
Three terms commonly encountered are:
JSON-LD
Microdata
RDFa
For Google Search implementations, JSON-LD is particularly important. JSON-LD stands for JavaScript Object Notation for Linked Data. Instead of requiring structured data attributes to be woven throughout visible HTML elements, JSON-LD can describe entities and their properties within a dedicated script block.
A simplified product example looks like this:
<script type="application/ld+json">
{ "@context": "https://schema.org", "@type": "Product", "name": "Atlas Desk Lamp", "description": "A compact desk lamp designed for modern workspaces.", "offers": { "@type": "Offer", "price": "59.00", "priceCurrency": "GBP" }
}
</script>
Two elements here are particularly important.
@context identifies the vocabulary being used.
@type identifies the type of entity being described.
The remaining structured data properties provide the machine-readable details associated with that entity.
JSON-LD therefore separates much of the structured data implementation from the presentation layer. Designers can concentrate on the user-facing interface while developers or a content management system can generate structured information from the same underlying content.
That separation can be particularly useful for ecommerce sites with hundreds or thousands of dynamically generated pages.
But there is an important caveat.
Structured data should describe the page that actually exists.
It isn't a licence to tell search engines something different from what visitors see.
Structured Data and Rich Results: What It Can — and Cannot — Do
This is where exaggerated SEO claims need to be stripped away.
Structured data can help Google and other search engines understand page content and its context. Supported structured data can also make qualifying pages eligible for particular search features or richer search appearances.
Depending on the content and the search engine's supported features, enhanced search results may expose additional information beyond a conventional blue link.
That can make search appearance more informative and, in appropriate circumstances, may influence how users interact with a result.
But three distinctions matter:
implementing schema markup does not mean a rich result is guaranteed;
eligibility for enhanced search features is not the same as guaranteed visibility; and
structured data should not be described as a magic switch for higher organic rankings.
The more useful goal is clarity.
You are reducing ambiguity about content meaning.
You are providing structured clues about entities and their properties.
You are helping search engines classify information.
And where supported, that information can contribute to enhanced search experiences.
For an ecommerce business, this is one reason a broader technical review can be valuable. A free ecommerce website audit can help reveal whether issues elsewhere in a site — from content structure to technical implementation — deserve attention alongside schema markup.
Why Structured Data Should Start at the Design Stage
Structured data is often treated as the final task on an SEO checklist:
Design the website. Build it. Add content. Launch it. Then add schema.
That order can work, but it misses a larger opportunity.
When structured data is considered during web design, it encourages the team to think deliberately about the underlying information model.
For example, if every product page needs a product name, description, image, price, availability and brand, those aren't merely visual components.
They are data fields.
If an article needs an author, publication date, headline and image, those are also data fields.
The visual page and the machine-readable description can therefore originate from the same structured content.
This approach creates several practical advantages:
page templates become more consistent;
CMS fields can map predictably to schema properties;
dynamic structured data becomes easier to maintain;
discrepancies between visible content and structured data can be reduced;
structured data validation becomes easier to systematise; and
future templates can inherit an established schema markup strategy.
In other words, structured data stops being an SEO accessory.
It becomes part of the web design system itself.
And that changes how we should approach the next question: which structured data should actually be implemented, where should it appear, and how do you prevent an ambitious schema strategy from becoming inaccurate, bloated or difficult to maintain?
Choosing the Right Schema for the Right Page
The temptation with structured data is to add as much as possible.
If Product is useful, why not add Organization, Review, FAQ, Article, VideoObject, LocalBusiness and anything else that seems vaguely relevant?
Because structured data works best when it is specific, accurate and genuinely representative of the page content.
The starting point shouldn't be:
"Which schema types can we squeeze onto this page?"
It should be:
"What does this page contain, and which structured data accurately describes it?"
That subtle change in thinking makes a substantial difference.
A product page, for example, naturally lends itself to Product structured data. The product may have an associated Offer, while genuine ratings displayed on the page might be represented using AggregateRating.
An editorial article has a different information model entirely.
Its important properties could include:
headlineauthordatePublishedimagedescription
An organisation has another set of characteristics. An event has another. A recipe has another.
The content type should inform the schema type — not the other way around.
Matching page intent to structured data
A simple planning framework might look like this:
Page/content type | Potential schema concepts | Information being described |
|---|---|---|
Product page |
| Product, price, currency, availability and ratings |
Blog article |
| Article, author and publication information |
Business information |
| Brand or company information |
Breadcrumb navigation |
| Position within the site's hierarchy |
Recipe |
| Ingredients, instructions and nutrition |
Event |
| Event details, date and location |
Software page |
| Application information |
Video page |
| Video content and associated information |
The crucial word is potential.
A schema type being available does not automatically mean it belongs on every remotely related webpage.
That distinction protects the integrity of your structured data strategy.
Build Structured Data Around Entities, Not Keywords
This is where structured data starts to reveal something bigger about modern search.
SEO has historically encouraged website owners to think heavily in terms of keywords.
A page targets a phrase. Related phrases are included. Titles and headings are optimised. Internal links reinforce topical relationships.
Structured data introduces another way of thinking:
entities and relationships.
Consider an online store selling one proprietary brand.
At the website level, there is an organisation.
That organisation has a name, URL, identity and potentially other associated properties.
The organisation creates or sells products.
Each product has attributes.
A product may have an offer.
That offer may have a price, currency and availability.
The product may also have legitimate customer reviews and an aggregate rating.
Those aren't simply keywords sitting beside each other on a webpage. They are interconnected pieces of information.
Conceptually:
Organization │ ├──────── Brand │ ▼ Product │ ├──────── Offer │ ├── price │ ├── priceCurrency │ └── availability │ └──────── AggregateRating ├── ratingValue └── ratingCountThis is content modelling meeting entity-based SEO.
The same principle extends beyond ecommerce.
An Article can connect to an author.
An Event can connect to a location.
A Recipe can connect ingredients to instructions and nutritional information.
A VideoObject can describe a video embedded within a page.
Structured data gives those relationships a machine-readable form.
Why entity relationships matter in web design
Good web design already creates relationships visually.
A product title sits near its photograph.
A price sits beside an add-to-cart button.
Breadcrumbs show where the current page sits within the website architecture.
An author's name appears underneath an article title.
Humans infer those relationships partly from proximity, hierarchy, typography and convention.
Machines don't necessarily interpret visual hierarchy in exactly the same way.
Structured data provides an additional semantic representation.
That's why semantic markup and visual design should complement one another rather than exist as separate projects.
Structured Data for Ecommerce Websites
For ecommerce businesses, Product structured data is one of the most obvious applications.
A well-constructed product page already contains a highly organised collection of facts:
What is this?
The product name and description answer that.
What does it look like?
The product imagery answers that.
How much does it cost?
The price and currency answer that.
Can I buy it?
Availability helps answer that.
What do customers think?
Where legitimate reviews are present, ratings and review content may answer that.
Much of the information needed for structured data therefore already exists.
The challenge is making sure the machine-readable version accurately corresponds with the customer-facing version.
Product and Offer
At a conceptual level, Product describes the item.
Offer describes an offer relating to that item.
That distinction allows information such as the following to be represented in a structured way:
Product
│
├── name
├── description
├── image
└── offers │ └── Offer ├── price ├── priceCurrency └── availability
This is more expressive than placing the phrase "£49.99 in stock" somewhere in HTML and leaving machines to determine exactly what the information represents.
The structured representation can make the relationship explicit.
Keep price and availability data synchronised
Dynamic ecommerce data creates an important implementation challenge.
Imagine the visible product page says:
£44.99 — In Stock
but an old JSON-LD block says:
£49.99 — Out of Stock
Now the website is presenting contradictory information.
That is precisely the kind of problem a scalable implementation should avoid.
Where practical, visible product information and structured data should draw from the same underlying source.
For example:
Product database / CMS │ ├──────────────► Visible product page │ └──────────────► JSON-LD structured dataChange the price once.
Update the source data once.
Allow both representations to reflect that change.
This is one reason structured data architecture deserves consideration during web development rather than being bolted onto a finished website manually.
Structured Data Should Be Part of Your CMS Architecture
A content management system can turn schema implementation from a repetitive manual exercise into a predictable process.
Imagine a blog publishing interface containing fields for:
article title;
description;
author;
publication date;
featured image; and
article body.
Those fields already form a basic content model.
Rather than asking an editor to manually write JSON-LD whenever an article is published, a page template can potentially map the appropriate CMS fields to corresponding structured data properties.
The same principle is even more valuable in ecommerce.
A product management system may already know the:
product name;
SKU;
description;
image;
brand;
price;
currency; and
availability.
That structured content can potentially drive both the visual interface and the machine-readable representation.
Dynamic structured data
This is the difference between static schema markup and a more scalable implementation.
Static structured data might be manually written for one page.
Dynamic structured data is generated according to the content associated with a page or template.
For a large website, dynamic generation can offer significant operational advantages.
It can improve:
Consistency — similar pages follow the same schema implementation.
Scalability — new pages can inherit appropriate structured data.
Maintainability — changes can be made at template level rather than page by page.
Accuracy — structured properties can pull from the same data used by visible content.
Quality control — validation can focus partly on predictable templates rather than entirely bespoke implementations.
However, automation introduces its own danger.
An error in one manually coded page affects one page.
An error in a template can potentially affect hundreds or thousands.
So automation should be paired with testing.
Structured Data Validation: Never Assume the Markup Works
A JSON-LD block can look perfectly reasonable to a human and still contain problems.
Perhaps a required value is absent.
Perhaps a property is being used incorrectly.
Perhaps the generated markup contains malformed syntax.
Perhaps structured information no longer matches visible page content.
Or perhaps a developer has implemented a valid Schema.org type while assuming that validity automatically means eligibility for a particular Google Search feature.
These are different questions.
That is why structured data validation and structured data testing should be built into the workflow.
A practical validation workflow
A sensible process can be broken into five stages:
Identify the page's primary content and entities.
Select appropriate structured data types and properties.
Generate or implement the markup.
Test the implementation and investigate errors or warnings.
Monitor live pages after deployment.
Tools such as Google's Rich Results Test can help assess supported structured data in relation to rich-result eligibility, while Google Search Console can provide ongoing information about detected structured data and relevant search enhancements.
A general schema validator can serve a somewhat different purpose: checking the structured data against the broader Schema.org vocabulary.
That distinction matters.
Schema validity and search-feature eligibility aren't necessarily identical things.
A piece of markup can use Schema.org vocabulary without necessarily corresponding to a search enhancement supported by a particular search engine.
Errors, Warnings and the Danger of "More Schema"
Structured data can become surprisingly noisy.
A website owner discovers schema markup, installs a plugin or generator, enables every available setting and suddenly each page contains a sprawling collection of types and properties.
More code has been created.
More meaning has not necessarily been created.
A better structured data strategy prioritises accuracy, relevance and completeness where appropriate over sheer volume.
Ask:
Does this property accurately describe visible content?
Is the entity actually represented on this page?
Is the value current?
Can it be maintained reliably?
Does the relationship between nested entities make sense?
Are we generating conflicting entities elsewhere in the template?
Are we adding markup because it improves machine understanding, or simply because the field exists?
This is particularly important when several systems can generate schema simultaneously.
A CMS theme might output structured data.
An SEO plugin might output more.
An ecommerce application might generate product markup.
A custom script might add another layer.
Individually, each implementation may appear sensible.
Collectively, they can produce duplicated or contradictory information.
Schema duplication deserves attention
Suppose one page produces two Product entities.
One says:
price: £79
availability: InStock
The other says:
price: £89
availability: OutOfStock
Which representation should a machine trust?
The ideal structured data architecture avoids creating that question in the first place.
Before adding new schema, therefore, audit what the site already produces.
Look at the rendered page.
Inspect the structured data.
Understand which system generates each block.
Only then decide what needs to be added, removed or consolidated.
Designing Page Templates With Structured Data in Mind
This is where Harnessing the Power of Structured Data in Web Design becomes a genuine design methodology rather than an SEO technique.
Take a product page template.
A conventional design process might specify:
Product image
Product title
Price
Description
Variant selector
Availability
Add-to-cart button
Reviews
Related products
A structured-data-aware process asks an additional set of questions:
Visible component | Content model | Potential semantic relationship |
|---|---|---|
Product title | Product name |
|
Main image | Product image |
|
Description | Product description |
|
Price | Offer price |
|
Currency | Offer currency |
|
Stock state | Availability |
|
Rating | Aggregate rating |
|
Review information | Reviews | Product/review relationship |
Now design, development and content modelling begin to speak the same language.
The designer understands which information is essential.
The developer understands where it comes from.
The content team understands which fields need to be maintained.
The SEO implementation has a predictable source of structured information.
And users still get the polished visual interface they actually came to see.
Semantic HTML and Structured Data Work at Different Layers
It's worth separating semantic HTML from structured data because they're sometimes collapsed into one idea.
Semantic HTML uses meaningful HTML elements to describe the role of content within the document.
For example:
<article> <header> <h1>Article Title</h1> </header> <p>Article content...</p>
</article>
Elements such as <article>, <nav>, <main>, <section>, <header> and <footer> can make document structure more meaningful than a page assembled entirely from generic <div> elements.
Structured data operates at another semantic layer.
It can describe what an entity is and which properties belong to it.
The two approaches aren't competitors.
They are complementary.
A strong web implementation can combine:
accessible page design + semantic HTML + logical information architecture + useful content + accurate structured data.
That combination is much more compelling than viewing schema markup as an isolated SEO trick.
What About Microdata and RDFa?
JSON-LD isn't the only format associated with structured data.
Microdata and RDFa can embed structured information more directly within HTML.
Conceptually, the difference can be thought of like this:
JSON-LD
Structured information is generally represented in a dedicated JSON-LD block.
Visible HTML
+
JSON-LD description
Microdata / RDFa
Semantic attributes are incorporated within the HTML markup itself.
HTML + structured attributes intertwinedEach approach has technical characteristics, but for many modern implementations JSON-LD offers an attractive separation between visible presentation and machine-readable data.
That separation can make template management cleaner, particularly when structured data is dynamically generated from a CMS or ecommerce platform.
The important consideration isn't merely the format.
It's whether the resulting data is correct, maintainable and representative of the page.
Structured Data, JavaScript and Modern Front-End Development
Modern websites aren't always delivered as simple static HTML documents.
JavaScript frameworks, client-side rendering, server-side rendering and dynamically populated components can all influence when and how page content becomes available.
Structured data therefore needs to be considered within the site's broader rendering architecture.
If JSON-LD is generated dynamically, developers should verify the actual output rather than assuming that because a component should generate structured data, the final page necessarily contains what was intended.
That means testing the rendered result.
It also means checking what happens when:
product information changes;
a product becomes unavailable;
content is removed;
a component fails;
a page template is redesigned;
JavaScript behaviour changes;
CMS fields are empty; or
multiple components reference the same entity.
Structured data is data.
And data quality needs maintenance.
Structured Data Is Not a Substitute for Good Web Design
There is an important point that can easily disappear in all this technical detail.
A perfectly marked-up bad page is still a bad page.
Structured data cannot compensate for:
confusing navigation;
weak product descriptions;
poor information architecture;
inaccessible interfaces;
misleading content;
painfully slow interactions;
broken layouts; or
an unclear customer journey.
Schema markup describes information.
It doesn't magically improve the underlying information.
The strongest implementation begins with a page that already works for people and then makes its meaning clearer to machines.
That gives us a useful principle:
Design for humans. Structure for machines. Make the underlying information consistent for both.
Once that foundation is established, the final challenge is turning structured data from a one-off development project into an ongoing system — deciding what to measure, how to monitor it, how it interacts with technical SEO and search visibility, and how to build a structured data strategy that remains useful as the website evolves.
Turning Structured Data Into an Ongoing Strategy
Implementing structured data isn't the finish line.
Websites change.
Products disappear. Prices move. Articles are updated. Templates evolve. Reviews accumulate. CMS plugins are replaced. JavaScript gets rewritten. Search engines adjust the search features they support.
A structured data implementation that was accurate twelve months ago may not accurately represent the website today.
That means structured data strategy needs maintenance.
The objective is not simply to launch valid schema markup. It is to create a system in which structured information continues to reflect the content users actually see.
A sustainable process might look something like this:
Content modelling ↓
Page templates ↓
Schema implementation ↓
Structured data validation ↓
Deployment ↓
Monitoring ↓
Content/template changes ↓
Revalidation
Notice the loop.
There is no permanent "finished" state.
For ecommerce websites in particular, the underlying data can change constantly. Product prices, availability, images, descriptions and ratings may all be dynamic.
The structured representation needs to keep pace.
Monitor Structured Data After Launch
Testing before deployment is essential.
Testing afterwards is equally important.
A development environment can tell you whether an implementation works under controlled conditions. A live website tells you whether it continues working when real products, real content and real template variations enter the picture.
Monitoring should therefore become part of technical SEO maintenance.
Depending on the implementation, this can involve:
checking representative URLs with the Rich Results Test;
reviewing relevant reports in Google Search Console;
monitoring structured data errors and warnings;
inspecting pages after major template releases;
checking schema when CMS functionality changes;
reviewing dynamic product information;
testing newly introduced page types; and
periodically comparing machine-readable data with visible page content.
The last point is especially important.
A validator may tell you that your JSON-LD is syntactically acceptable.
It cannot make every strategic decision for you.
You still need to ask whether the data accurately describes the page.
Don't Confuse Schema Validity With Rich-Result Eligibility
Several concepts are easily bundled together:
valid structured data, Schema.org vocabulary, Google-supported structured data and rich-result eligibility.
They overlap, but they aren't identical.
Schema.org provides a broad vocabulary for describing entities and relationships on the web. Search engines may support particular subsets of structured data for specific search experiences.
Consequently, being able to describe something with Schema.org doesn't automatically mean Google Search will display a special search feature for it.
Likewise, implementing supported structured data does not guarantee that an enhanced result will appear.
This distinction is useful because it keeps expectations realistic.
Structured data has value as a way of explicitly describing content.
Rich-result eligibility is one possible application of that structured information.
Think beyond the shiny search result
It is understandable that businesses focus on rich snippets and enhanced search results. They are visible.
Machine understanding isn't.
But reducing structured data to "code for rich snippets" misses much of the underlying idea.
The broader concept is knowledge representation.
A page contains information.
Structured data expresses that information in a predictable machine-readable form.
That can help systems interpret:
what the primary entity is;
which attributes belong to it;
how entities relate;
what particular values represent; and
how information should be classified.
Seen from that perspective, structured data is less of an SEO decoration and more of a bridge between human-facing content and machine interpretation.
Can Structured Data Improve SEO?
This question deserves a careful answer.
Structured data is often presented as though adding schema markup automatically produces higher organic rankings.
That is too simplistic.
A more useful way to think about its SEO role is through a chain of possible effects:
better-described content → improved machine understanding → eligibility for supported search features → potentially more informative search appearance → possible changes in user behaviour
There are several qualifications in that chain.
Eligibility isn't a guarantee of a rich result.
A richer search appearance doesn't guarantee a higher click-through rate.
A higher click-through rate doesn't automatically mean more conversions.
And structured data itself doesn't rescue a page that otherwise provides little value.
Where structured data fits into technical SEO
Structured data should therefore sit alongside, rather than replace, fundamentals such as:
crawlability;
indexability;
internal linking;
logical website architecture;
useful page content;
descriptive titles;
mobile usability;
performance;
accessibility;
canonicalisation; and
sound HTML.
Think of it as another layer of communication.
Your content tells people what the page means.
Your information architecture establishes where that page belongs.
Your internal links establish relationships across the site.
Your HTML creates document structure.
Your structured data supplies an explicit machine-readable description of relevant entities and properties.
These layers work together.
Search Visibility Is Only Part of the Story
Structured data discussions naturally gravitate towards search visibility, SERPs, rich results, organic traffic and click-through rate.
Those are reasonable considerations.
But structured content can also encourage better website architecture behind the scenes.
To produce reliable structured data, a business needs to know what its content actually is.
Is this page a product?
Who is the author of this article?
Which organisation owns this content?
What is the canonical product name?
Where does the price originate?
What is the current availability state?
Which image represents the entity?
Those questions expose weaknesses in content architecture remarkably quickly.
If nobody can confidently answer them, generating consistent schema markup will be difficult.
Structured data can therefore act as a useful test of content maturity.
If your organisation cannot clearly model its own information, it will struggle to describe that information clearly to machines.
This is why structured data projects can spill productively into conversations about taxonomy, page templates, CMS fields, data modelling and website governance.
Structured Data and the Knowledge Graph Mindset
Another useful conceptual shift is moving from individual pages towards interconnected entities.
Traditional website thinking often looks like this:
Homepage
├── Category page
│ ├── Product page
│ └── Product page
└── Blog ├── Article └── Article
That hierarchy is useful.
But an entity-oriented model asks different questions.
Which organisation owns the site?
Which brand is associated with the products?
Which products belong to which categories?
Which authors created which articles?
Which articles discuss which products or concepts?
Which offers belong to which products?
Which reviews refer to which items?
Now the website starts to resemble a network:
Organization ───── Brand │ │ │ ▼ └────────── Product │ ┌───────┴────────┐ ▼ ▼ Offer AggregateRating │ ▼ Price / AvailabilityThis doesn't mean every relationship needs to be forced into one enormous JSON-LD graph.
It means your content model should recognise that webpages contain entities which exist in relationships with other entities.
That mindset can improve consistency long before any schema is generated.
Structured Data and Accessibility Are Not the Same Thing
Because semantic HTML, machine-readable content and accessibility frequently appear in the same conversations, another distinction is worth making.
Structured data is not a substitute for accessible web development.
Adding JSON-LD does not repair an inaccessible navigation menu.
It doesn't give an image appropriate alternative text.
It doesn't fix poor keyboard navigation.
It doesn't create sufficient contrast.
It doesn't establish a sensible heading hierarchy for users.
Semantic HTML and accessibility practices directly affect how people and assistive technologies interact with a webpage. Structured data serves a different purpose.
A well-designed website should consider both.
The goal is not:
humans or machines.
It is:
humans and machines, with the appropriate implementation for each.
Common Structured Data Mistakes to Avoid
The principles discussed throughout this article point towards several recurring mistakes.
1. Adding schema that doesn't represent visible content
Structured data should describe what is genuinely present and represented by the page.
Don't create a richer machine-readable story than the page itself can support.
2. Hard-coding dynamic information
A manually entered price may be correct today and wrong tomorrow.
Where values change regularly, consider whether structured data can draw from the same underlying source as visible content.
3. Assuming more properties automatically mean better SEO
Completeness matters where properties are relevant, but meaningless volume doesn't.
Accurate structured information is the goal.
4. Installing multiple schema generators without auditing the output
Themes, plugins, apps and custom code can all produce structured data.
Know which system owns which entity.
5. Ignoring nested relationships
A price isn't simply a random number attached to a product.
It can belong to an Offer, which itself relates to a Product.
Understanding these relationships is fundamental to good schema implementation.
6. Treating a successful validation test as the end of the project
Websites evolve.
Revalidate after significant changes.
7. Expecting guaranteed rich results
Correct implementation can establish eligibility where supported. Search appearance remains dependent on the search engine and the particular query and context.
8. Using structured data to compensate for poor content
Schema markup can describe a weak product page exceptionally well.
It will still be a weak product page.
9. Forgetting the content management workflow
If editors can't reliably maintain the information feeding structured data, accuracy will deteriorate.
10. Designing first and thinking about information last
Beautiful interfaces work better when the underlying content model is equally deliberate.
A Structured Data Checklist for Web Designers
Before launching a new page template, work through this practical checklist.
Content and entity identification
What is the primary purpose of the page?
What is its primary entity?
Are secondary entities genuinely relevant?
Are relationships between those entities understood?
Does the structured information correspond to visible page content?
Schema selection
Is an appropriate Schema.org type available?
Are the selected schema properties relevant?
Are nested entities represented logically?
Is unnecessary markup being added simply because it is available?
Implementation
Is JSON-LD appropriate for the implementation?
Is the markup generated manually or dynamically?
Where does each property get its value?
Can dynamic values become stale?
Could another plugin, theme or application generate duplicate schema?
Testing
Is the syntax valid?
Has structured data validation been performed?
Has the page been checked using appropriate testing tools?
Are errors understood?
Have warnings been reviewed rather than automatically ignored?
Has the rendered production page been tested?
Maintenance
Who owns the structured data implementation?
What happens when the page template changes?
What happens when a CMS field is removed?
Are product prices and availability automatically synchronised?
Will major website releases trigger revalidation?
Is Google Search Console being monitored where relevant?
If those questions have clear answers, structured data is becoming part of the website's architecture rather than an afterthought.
Measuring the Impact of Structured Data
Measurement also needs nuance.
It can be tempting to implement schema markup and then watch organic rankings for a dramatic jump.
That approach assumes a direct relationship that shouldn't automatically be expected.
Instead, consider several dimensions.
Search appearance
Monitor whether eligible pages begin appearing with relevant search enhancements where available.
Search performance
Review impressions, clicks and click-through rate in appropriate search reporting.
Look for patterns rather than assuming every change is caused by schema.
Coverage and validity
Track whether important templates continue producing valid structured data.
If hundreds of products suddenly develop errors after a deployment, that is an operational signal worth investigating.
Data consistency
Periodically compare visible information with its structured equivalent.
For ecommerce pages, pay particular attention to values such as:
price;
currency;
availability;
product identity;
ratings; and
review counts.
Template health
Structured data errors clustered around a particular page type may expose a deeper CMS or template problem.
This is another reason schema monitoring can be useful even beyond search appearance.
Don't Optimise for CTR at the Expense of Accuracy
Rich search appearances can naturally lead marketers towards another question:
How can we make our result stand out?
That's reasonable.
But structured data shouldn't become a vehicle for embellishment.
If information is represented as a rating, review, price or availability state, it needs to accurately correspond with the underlying content and implementation requirements.
The aim is not to make a search result look as elaborate as possible.
The aim is to make information understandable.
If that clearer information subsequently supports an enhanced display and contributes to stronger user engagement, that is a useful outcome.
But accuracy comes before decoration.
The Future Is Increasingly Machine-Readable
Websites are consumed by far more than human visitors looking at screens.
Search crawlers interpret them.
Assistive technologies interact with them through their own mechanisms.
Applications retrieve information.
Automated systems classify content.
Search platforms attempt to understand entities and relationships.
And the broader web continues to generate an enormous quantity of information that machines need to interpret.
This makes structured content increasingly important as a design consideration.
Not because every webpage needs every available schema type.
Not because structured data guarantees rankings.
And certainly not because adding more JSON-LD automatically creates a better website.
It matters because ambiguity is expensive for machines.
Structured information reduces some of that ambiguity.
A well-modelled product is easier to describe consistently than an assortment of disconnected text fields.
A clearly identified organisation is more explicit than hoping its identity can always be inferred.
An article with an established author, publication date and headline has a clearer information model than an unstructured block of content.
The underlying principle is simple:
Know what your content represents before asking machines to understand it.
Bringing Structured Data Into the Web Design Process
So when should structured data enter a web design project?
Earlier than many teams expect.
During discovery
Identify the important content types, entities and relationships.
During information architecture
Determine how those entities fit within the website hierarchy.
During content modelling
Define the fields needed to represent each entity accurately.
During UX and interface design
Make sure important information is genuinely available to users rather than existing only for machines.
During development
Map appropriate content fields to structured data properties and implement a maintainable architecture.
During quality assurance
Validate representative page templates and unusual edge cases.
After launch
Monitor, test and revisit the implementation as the website evolves.
This turns schema markup from a final SEO ticket into a cross-disciplinary concern spanning web design, development, content strategy and technical SEO.
A Better Way to Think About Structured Data
Perhaps the easiest mistake is thinking of structured data as something you add to a website.
A more mature approach is to think about the website itself as structured information.
Your visual design is one representation of that information.
Your HTML is another.
Your CMS database is another.
Your internal linking structure expresses another set of relationships.
Your structured data provides another representation intended to make particular meanings explicit to machines.
When those layers originate from a coherent content model, they reinforce one another.
When they don't, inconsistencies appear.
That is why the best schema implementation often begins nowhere near a <script> tag.
It begins with questions.
What are we describing?
Which information defines it?
Where does that information come from?
How is it presented to users?
How should machines interpret it?
Answer those questions first and the markup becomes much easier to reason about.
Final Thoughts: Harnessing the Power of Structured Data in Web Design
Harnessing the Power of Structured Data in Web Design isn't about stuffing a website with schema types, chasing every possible rich snippet or turning an elegant interface into a technical SEO experiment.
It is about clarity.
Clear content.
Clear entities.
Clear relationships.
Clear page architecture.
Clear signals for machines.
A strong implementation connects semantic HTML, structured content, Schema.org vocabulary, JSON-LD, information architecture and thoughtful web development into one coherent system.
For ecommerce websites, that can mean accurately describing products, offers, prices, availability and legitimate ratings.
For publishers, it can mean clearly representing articles, authors, images and publication information.
For businesses more generally, it means recognising that modern web design has both a visual layer and a data layer.
People need an experience that is useful, accessible, persuasive and easy to navigate.
Machines need information they can interpret.
Structured data sits between those needs — not replacing good design or good SEO, but adding a machine-readable layer of meaning to the content you've already worked hard to create.
The most useful principle to carry forward is therefore also the simplest:
Design for people. Structure information deliberately. Describe it accurately for machines.
Do that consistently, and structured data stops being a collection of mysterious properties hidden in the source code.
It becomes part of how the website communicates.
Frequently Asked Questions About Structured Data in Web Design
1. Does every page on a website need structured data?
No. Structured data should be implemented where it accurately describes meaningful content or entities on a page.
A website doesn't become better simply because every URL contains schema markup. The more useful approach is to identify important page types and determine whether relevant Schema.org vocabulary can accurately represent their content.
For example, product pages, articles and certain navigational elements may have obvious structured data applications. Other pages may have little additional information worth expressing through schema.
Relevance and accuracy are more important than site-wide schema coverage.
2. Can you use more than one schema type on the same webpage?
Yes. A webpage can contain multiple entities and schema types when they accurately represent its content.
For example, a page could contain a primary Product entity connected to an Offer, while other appropriate structured information describes different elements of the page.
The important consideration is the relationship between those entities.
Adding multiple schema types simply because they are available can make an implementation unnecessarily complicated. Each entity should have a clear purpose, accurately represent the page content and be connected logically where relationships exist.
Think of structured data as a model of the page's information, rather than a checklist of schema types to accumulate.
3. Should structured data be identical on desktop and mobile versions of a website?
The underlying structured information should remain consistent with the content users can access on the relevant version of the page.
If the same product is represented with different prices, availability or other important properties depending on how a page is rendered, inconsistencies can create confusing signals.
Responsive web design generally makes this easier because the same underlying page and content can adapt visually to different screen sizes.
Whatever front-end approach is used, the central principle remains the same:
The structured data should accurately represent the content and entities available on the page rather than becoming a separate version of reality.
4. How often should structured data be audited?
There isn't one universal timetable because websites change at very different rates.
A small website with relatively static content may require less frequent attention than an ecommerce store where products, prices, availability, reviews and templates change regularly.
Rather than relying exclusively on a calendar, consider auditing structured data after significant events such as:
a website redesign;
a CMS migration;
changes to product templates;
installing or replacing SEO plugins;
introducing new page types;
substantial JavaScript or front-end changes;
changes to the ecommerce platform; or
unexpected structured data errors appearing in monitoring tools.
Periodic checks can then supplement these event-driven audits.
5. Can structured data slow down a website?
Structured data itself is usually text-based and comparatively lightweight, but the way it is implemented still matters.
A concise JSON-LD block is very different from installing a large third-party application purely to generate a small amount of markup.
If several plugins, tag managers or JavaScript processes are being introduced to handle schema, their broader performance implications deserve consideration.
The objective should therefore be a clean, maintainable implementation rather than adding unnecessary technical complexity.
Where structured data can be generated efficiently from information the website already stores, there may be little reason to introduce an elaborate additional layer.
6. Should structured data be added manually or generated automatically?
Both approaches can work.
Manual implementation can make sense for a small number of relatively static pages because the developer has direct control over the markup.
Automatic or dynamic generation becomes much more attractive when a website contains large numbers of pages following consistent templates.
An ecommerce store with hundreds of products, for example, would generally benefit from structured data drawing information from the same underlying product data rather than requiring someone to manually update individual JSON-LD blocks whenever a price changes.
The trade-off is scale.
Automation can distribute good implementation across thousands of pages — but it can distribute an error just as efficiently.
Automated structured data therefore needs testing and ongoing quality control.
7. What happens if structured data contains information that isn't visible on the page?
That can create a mismatch between the machine-readable representation and the content presented to visitors.
Structured data should accurately describe the page rather than being used to manufacture information solely for search engines.
For example, marking up a rating that users cannot actually find in the represented content would raise a very different issue from accurately describing legitimate rating information associated with the product.
The safest principle is straightforward:
Don't use schema markup to claim something about a page that the page itself doesn't genuinely support.
This keeps structured data aligned with the content experience rather than creating two competing versions of the same webpage.
8. Can AI and automated tools generate structured data?
Yes. Automated systems can assist with identifying entities, suggesting schema types and generating JSON-LD from existing information.
That can make structured data generation considerably faster, particularly for repetitive implementations.
But generated markup should still be treated as an implementation requiring verification.
An automated system may misunderstand the primary entity, associate a value with the wrong property, invent a relationship that isn't supported by the page or generate technically plausible markup that doesn't accurately reflect the content.
AI can therefore be useful for assisting structured data workflows, but human oversight, validation and reliable source data remain important.
Automation makes generation easier.
It doesn't make accuracy automatic.
9. Can structured data help search engines understand a brand and its products?
Structured data can provide explicit machine-readable information about entities and relationships represented by a website.
For a single-brand ecommerce business, for example, the site may contain an Organization or relevant brand information alongside individual Product entities and associated offers.
That can create a clearer structured representation of concepts such as:
organisation → brand → product → offer
Structured data should not be treated as a shortcut to search-engine recognition, however. It is one layer of information alongside the website's visible content, architecture, internal relationships and wider search signals.
Its role is to reduce ambiguity and make relevant information more explicit, not to manufacture authority that doesn't otherwise exist.
10. What is the biggest structured data opportunity most web designers overlook?
It is probably not a particular schema type.
It is content modelling before the website is built.
When structured data is considered only after design and development are complete, the implementation has to work with whatever information architecture already exists.
When it is considered earlier, more useful questions emerge:
What entities will this website contain?
Which information defines each entity?
Where will that information be stored?
Which page templates will display it?
How are different entities related?
Which information changes dynamically?
Can visible content and structured data share the same source?
Those questions improve much more than schema markup.
They encourage clearer CMS architecture, more consistent templates, better organised content and a stronger relationship between web design, structured content, semantic markup and machine-readable data.
That is ultimately what Harnessing the Power of Structured Data in Web Design means: not simply adding code for search engines, but designing information deliberately enough that both people and machines can understand what the website is communicating.
